


Published: Oct 19, 2026
How AI Is Changing Digital Asset Management for Creative and Marketing Teams
Table of contents
Why the library is what makes the AI work
What AI does at each stage of an asset's life
How AI keeps feedback, approvals, and distribution tied to one source of truth
What AI should not decide
A short checklist for evaluating AI in a DAM
AI in digital asset management FAQs
Matthew Lucier, the Global Film Lead at Strava, once described a pattern that will sound familiar to anyone who runs a brand library: People open their old asset manager, can't find what they need, and fall back on the same five photos they already know are in there. Meanwhile, thousands of better shots sit in the archive, unsearchable, aging out of use.
That gap between what a team owns and what a team can actually find is the problem AI can actually solve by making files searchable by plain description and acting on the library itself. The result is less time spent cataloguing and more time spent using work that's already approved.
The role of AI in digital asset management with this lens is giving creative work a memory. This guide walks through what the AI can do at each stage of an asset's life, from the moment a file lands to the moment it ships across channels.
Why the library is what makes the AI work
Most "AI-powered DAM" marketing describes the model and skips the fuel. The context each asset carries, its tags, custom fields, version history, approval status, and usage rights, is what the AI actually draws on.
Library quality therefore, sets the ceiling on AI output. A messy archive produces messy results no matter how advanced the model.
Picture two ways to make a holiday campaign variant:
In the first, you prompt a blank model and hope it lands somewhere near your brand.
In the second, you ask an agent to work from the approved holiday shoot that already cleared legal review, with the right logos, colors, and crops built in.
The second path is faster and safer because the context already exists. The first path produces something you have to check from scratch every time. This is also why AI exposes a disorganized library rather than fixing one. If assets aren't searchable, the AI has nothing solid to retrieve, describe, or build on.
What AI does at each stage of an asset's life
AI earns its keep inside a DAM at four moments:
When a file first lands and needs to be understood
When someone needs to find it again
When the library itself needs cleaning up
When approved work needs to be adapted for channels
Each stage feeds the next. Good comprehension at ingest makes search work, strong search makes agent actions reliable, and clean context makes generative edits land on brand.
When a file lands: AI reads it so no one has to catalogue it
The first job of AI in digital asset management is comprehension at ingest, not organization. The system reads the file so the file can describe itself later, which removes the manual tagging step teams always abandon under deadline.
Here's what that looks like across formats, using Air as the example:
Images: Visual recognition and auto-tagging apply Smart Tags for concepts, colors, and objects, with Smart Summaries describing the shot.
Text inside files: OCR indexes text embedded in images and PDFs, and Document Intelligence indexes full slide decks for deep search.
Video: Video Intelligence generates time-synced transcripts in 100-plus languages, splits long clips into Smart Chapters, and writes AI summaries for quick skimming.
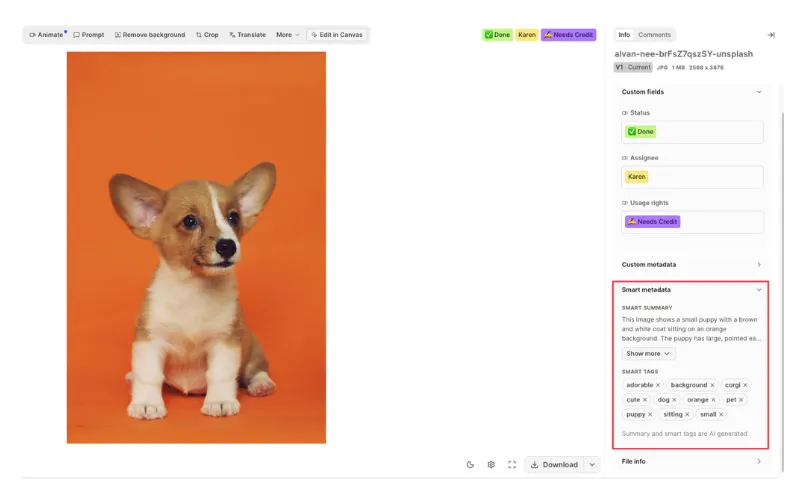 On top of the general layer sits a brand-specific one. Custom Object Recognition can be trained to spot your products and logos, and Facial Recognition tags the talent appearing in your campaigns.
The Infatuation, for example, were able to reap the benefits of DAM AI at this moment. Freelance photographers upload into a pre-built board, and Air auto-tags the photos on arrival with terms like "burger," "fries," "food," and "plate." Nobody renames hundreds of files by hand.
When someone needs it back: describing an asset instead of remembering its filename
Conversational search capabilities change how file retrieval works. Instead of guessing at folder paths or filenames, a marketing lead types "vertical crops from the spring shoot." The results come back based on what's inside the files because the search engine reads the metadata the ingest step created, which is why the two stages depend on each other.
Pairing a plain-language query with a reference image also surfaces comparable assets, which helps when a marketer has an example in mind but no name for it. Boards also let one approved file live in several places without duplicating storage, and scrubbable previews let a team confirm a file's contents before opening it.
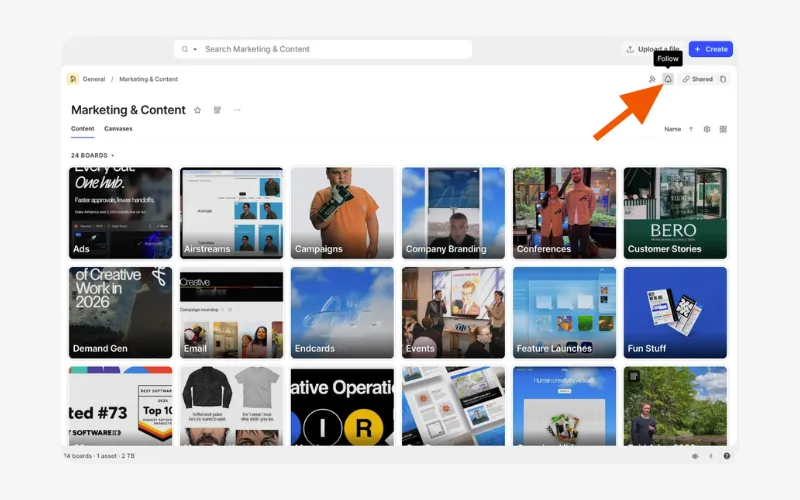 This is the direct fix for the "same five photos" trap Matthew Lucier mentioned. Discovery failure is what drives asset reuse down and reshoot budgets up, because teams can only reuse what they can find.
When the library needs cleaning up: AI as the one doing the admin
Air's agent for creative tasks moves AI from passive search to action. Users can describe a chore in plain language, and the agent carries it out across the library, with brand context already built in.
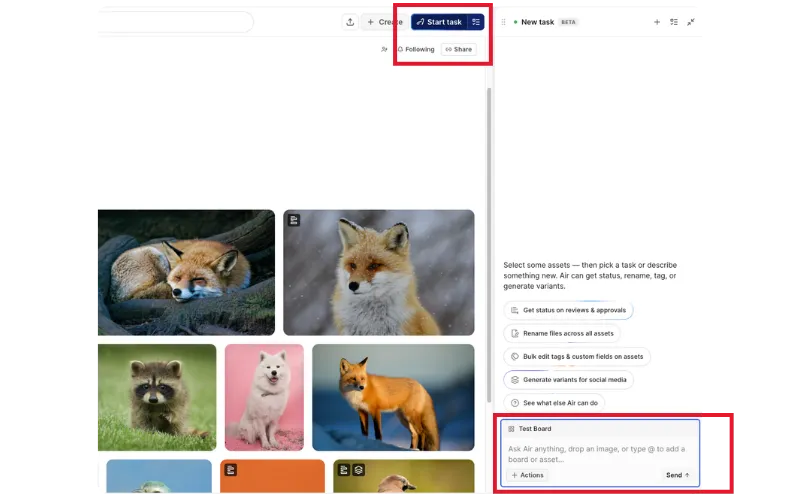 What's live (at the time of writing) maps to real creative-ops work:
Tag and rename at scale from a single instruction, so naming stays consistent across thousands of files.
Search then act on the results, like converting file types or adding a set to a board.
Get caught up instantly on approvals, comments, and board activity without clicking through everything.
This means a creative director could type something as direct as "Create a board with the approved assets from our last shoot" and get it back ready to use.
To keep expectations honest, scheduled multi-step workflows, runs across 10,000+ assets at once, and on-demand performance analytics are on Air's roadmap but not available (again, at the time of writing). Treat the agent as a fast assistant for today's housekeeping, not a fully autonomous operator yet.
When approved work needs to ship: adapting without starting over
The most useful generative AI in a DAM is one-to-many, not zero-to-one. This concept means scaling an asset that already cleared approval into every size and format a campaign needs, rather than inventing a new asset from scratch.
In Air, Context supplies the brand memory that makes this safe. Teams build brand kits with fonts, colors, logos, and usage rules, auto-detected from a website URL or added by hand.
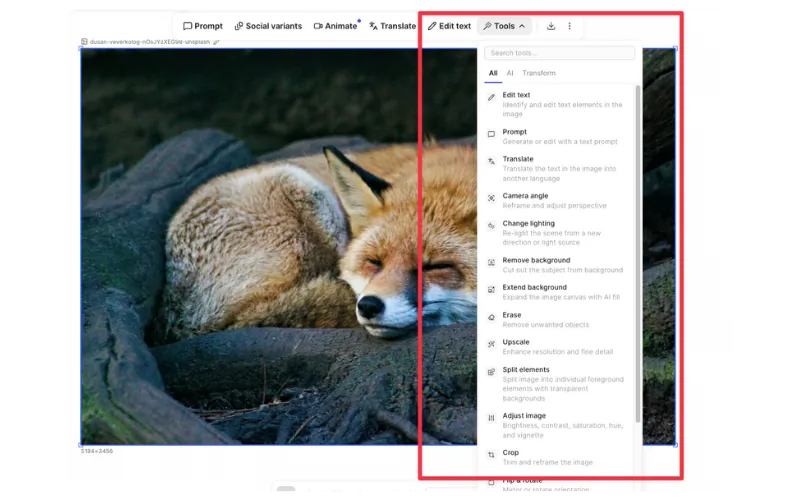 Air Canvas draws on them so outputs land on brand without extra review rounds. Here are a few practical edits creative and marketing teams repeat every week that Canvas handles:
Background removal for product shots and logos
Reframe and Smart Resize to hit channel specs while preserving layout and no-fly zones
Edit Text directly on an image when the source file isn't around
Batch edits applied across many assets at once
Image-to-video to animate a static asset
Skills turn any of these into institutional memory. Save a Canvas edit as a named, reusable workflow, then run it across a batch later so the whole team repeats it the same way.
How AI keeps feedback, approvals, and distribution tied to one source of truth
Governance is the part most AI DAM content skips, yet it’s what makes automation trustworthy. An agent that surfaces the wrong file fast is worse than no agent at all.
Before an agent hands over an asset, it has to know whether it’s the final version and whether it was approved. Air answers both by keeping that information on the file itself, not in email threads and spreadsheets.
Visual annotations and timestamped comments pin feedback to the exact spot or scene, and the approval decision is recorded on the same asset. So when the agent pulls a file, it gets what was approved, not whatever was uploaded last.
For sharing and distribution, the file stays tied to its source after it ships: CDN links point back to the master in Air, so an update shows up everywhere the file is live.
It's also worth noting, Air never uses customer files to train AI models.
What AI should not decide
Air does the tasks, you do the work. Execution and judgment are different jobs, and AI is good at only one of them.
Here's the split in practice:
What AI handles reliably: tagging, transcription, renaming, resizing, format conversion, and first-pass retrieval.
What a human still owns: final approval, brand judgment, rights and legal clearance, sensitive or talent-related content, and the call on what's worth making at all.
Notice that everything in the first group is repeatable and verifiable, while everything in the second involves a decision only a person should sign off on. What changes is the DAM manager's day is moving from cataloguing toward governance, taxonomy design, and helping the rest of the team use the system well.
A short checklist for evaluating AI in a DAM
Before you compare AI for digital asset management across vendors, bring a few pointed questions into the call. Each one tells you whether the AI is grounded in your library or just bolted on:
Question to ask | What it tells you |
Does the AI read video and documents, or only images? | A library that's mostly video or decks needs transcription and document indexing, not just image tags. |
Can it be trained on our products and logos? | Generic recognition misses the things your brand actually sells. |
Can search handle plain-language and visual queries? | Keyword-only search sends people back to guessing filenames. |
Can it act on the library, or only describe it? | Describing is useful; tagging and renaming at scale saves real hours. |
Do generative outputs inherit our brand rules? | Without brand context, every AI edit needs a full review round. |
Does approval status travel with the asset? | If it doesn't, the AI can surface work that was never cleared. |
Are our files used to train the vendor's models? | You want a clear no in writing. |
To get started with an AI DAM, go with one high-value use case instead of a full migration first, usually the archive your team searches most or the campaign with the most channel variants.
Run an audit by finding out what share of the current library is actually findable, and what the team has reshot or remade in the last quarter only because it couldn't locate the original. That audit tends to make a good case on its own.
AI's value in a DAM comes from the context around your assets, which is exactly why teams stop remaking what already exists and start building on what works. If you want to see that in practice, start a free workspace in Air today.
AI in digital asset management FAQs
What is the role of AI in digital asset management?
AI reads the content of your files, makes them searchable by plain description, and takes action on the library like tagging and renaming at scale. Its real value comes from the context around each asset, which is why a well-organized library produces far better AI results than a scattered one.
How does AI improve digital asset management for creative teams?
AI improves digital asset management by auto-tagging files on upload, letting people find assets by describing them, and adapting approved work for channels without rebuilding from the source. That removes the manual cataloguing that teams abandon under deadline and cuts the reshoots caused by unsearchable archives.
Will AI replace the person who manages our DAM?
No. AI changes what that person spends their day on, shifting them from renaming files toward governance, taxonomy design, and helping teams actually use the library, which is the higher-value work they were hired for.
Does a DAM use our files to train AI models?
Not in Air's case. Air never uses customer files to train AI models, so your assets stay your assets and are not fed into any training pipeline.
Can outside AI assistants connect to our digital asset library?
Yes. Through Air's MCP server on Business and Enterprise plans, external AI tools can connect to your library, so your approved assets, tags, and context become grounding for the tools your team already uses.
What can't AI do in a DAM?
AI handles repeatable, verifiable tasks like tagging, transcription, resizing, and first-pass search. It should not make final approval calls, brand judgments, rights and legal clearances, or decisions about sensitive content, which all stay with a person.
How is an AI DAM different from using AI image generators on their own?
A standalone image generator starts from a blank prompt with no memory of your brand or what's approved. An AI DAM grounds the model in your actual library, so it scales work that already cleared review instead of inventing something you have to check from scratch.